The day-90 email asking happy customers to refer a friend converts poorly. It is not because your customers don't like you. It's because propensity to refer peaks at specific product milestones, not at a fixed post-signup interval, and your happiest users may not have the network fit or timing to produce a conversion anyway. A referral propensity score models for what actually drives a closed referral, and this is how to build one.
- What referral propensity score means in a B2B SaaS context
- Why standard lead scoring fails to predict referral behavior
- The signal categories that drive referral propensity
- How to weight and combine signals into a composite score
- Building the training dataset from historical referral outcomes
- Applying the score to segment your referrable user base
- Timing: when in the customer lifecycle to act on a high score
- Adjustments for long sales cycles, niche markets and compliance-sensitive verticals
- Common model failures and how to avoid them
- Activating the score inside your referral program
- How Cello uses referral propensity logic for user-led growth
- Final thoughts on using referral propensity scores in B2B SaaS
TLDR:
- A referral propensity score predicts which users will produce converting referrals, beyond simply who likes your product or scores high on NPS
- Five signals drive the model: product usage depth, network position, relationship tenure, satisfaction proxies and external sharing behavior
- Segment scored users into three tiers: top 15-20% get direct in-product activation, middle 40-50% get milestone-based nurture and low scorers get excluded entirely
- A high score is a precondition, not a trigger: prompt only at value moments like workflow completion, feature mastery or a first expansion event
- Cello's behavioral milestone triggers and multi-campaign segmentation by user attributes map directly to this scoring logic, producing meaningfully higher sharing rates versus static prompts
What referral propensity score means in a B2B SaaS context
A referral propensity score is a per-user numerical estimate of how likely a given customer is to make a referral that actually converts, as distinct from one who clicks share or rates you a 9 on an NPS survey.
That distinction matters more than it sounds. NPS tells you who likes the product. Lead scoring tells you who might buy. Neither tells you who will bring someone else through the door and close them. In B2B SaaS, those are three completely different people, and conflating them is where most referral programs for SaaS break down.
General advocacy scoring, as a 2026 signal-based scoring paper on SSRN notes, measures readiness to advocate broadly across case study participation, review posts and community activity. Referral propensity is narrower: it predicts a specific economic action tied to a conversion event. A customer can be a loud advocate and a weak referrer, particularly where their peers are locked into competing tools or where compliance-sensitive environments limit vendor recommendations.
Propensity to refer also peaks at specific product milestones, not at a fixed post-signup interval, which is why a static trigger like day 90 misses most of the signal.
Why standard lead scoring fails to predict referral behavior
Standard lead scoring answers one question: will this person buy? It weights pricing page visits, email opens and demo requests because those signals predict purchase intent. Referral behavior follows a different logic.
Purchase intent peaks early in a user's relationship with the product. Referral intent peaks later, after someone has embedded the product into a workflow (a core pattern in referral marketing for B2B SaaS), built trust in its reliability and developed enough peer credibility to make a recommendation that lands. None of those conditions appear in a CRM engagement score.
NPS compounds the problem. A high score tells you a user would recommend the product in the abstract. It says nothing about whether they have the social capital to refer someone who will actually convert, whether their network contains ICP-fit buyers or whether they operate in a compliance environment where recommending vendors is restricted. Two users can score 10 on NPS and produce completely different referral outcomes.
Firmographic signals fail in a different direction. Company size and industry predict buying propensity reasonably well, but referral acts are driven by individual user behavior within an account, not account-level attributes. The champion who renews every year and attends every webinar may never refer anyone. The power user who quietly runs their entire workflow inside your product might refer three paying customers without ever opening a marketing email.
What lead scoring misses is the combination of product embeddedness, network fit and lifecycle timing. Repurposing an existing lead score for referral targeting produces poor segmentation and worse activation rates. This is a key reason B2B referral programs that convert require purpose-built approaches.
The signal categories that drive referral propensity
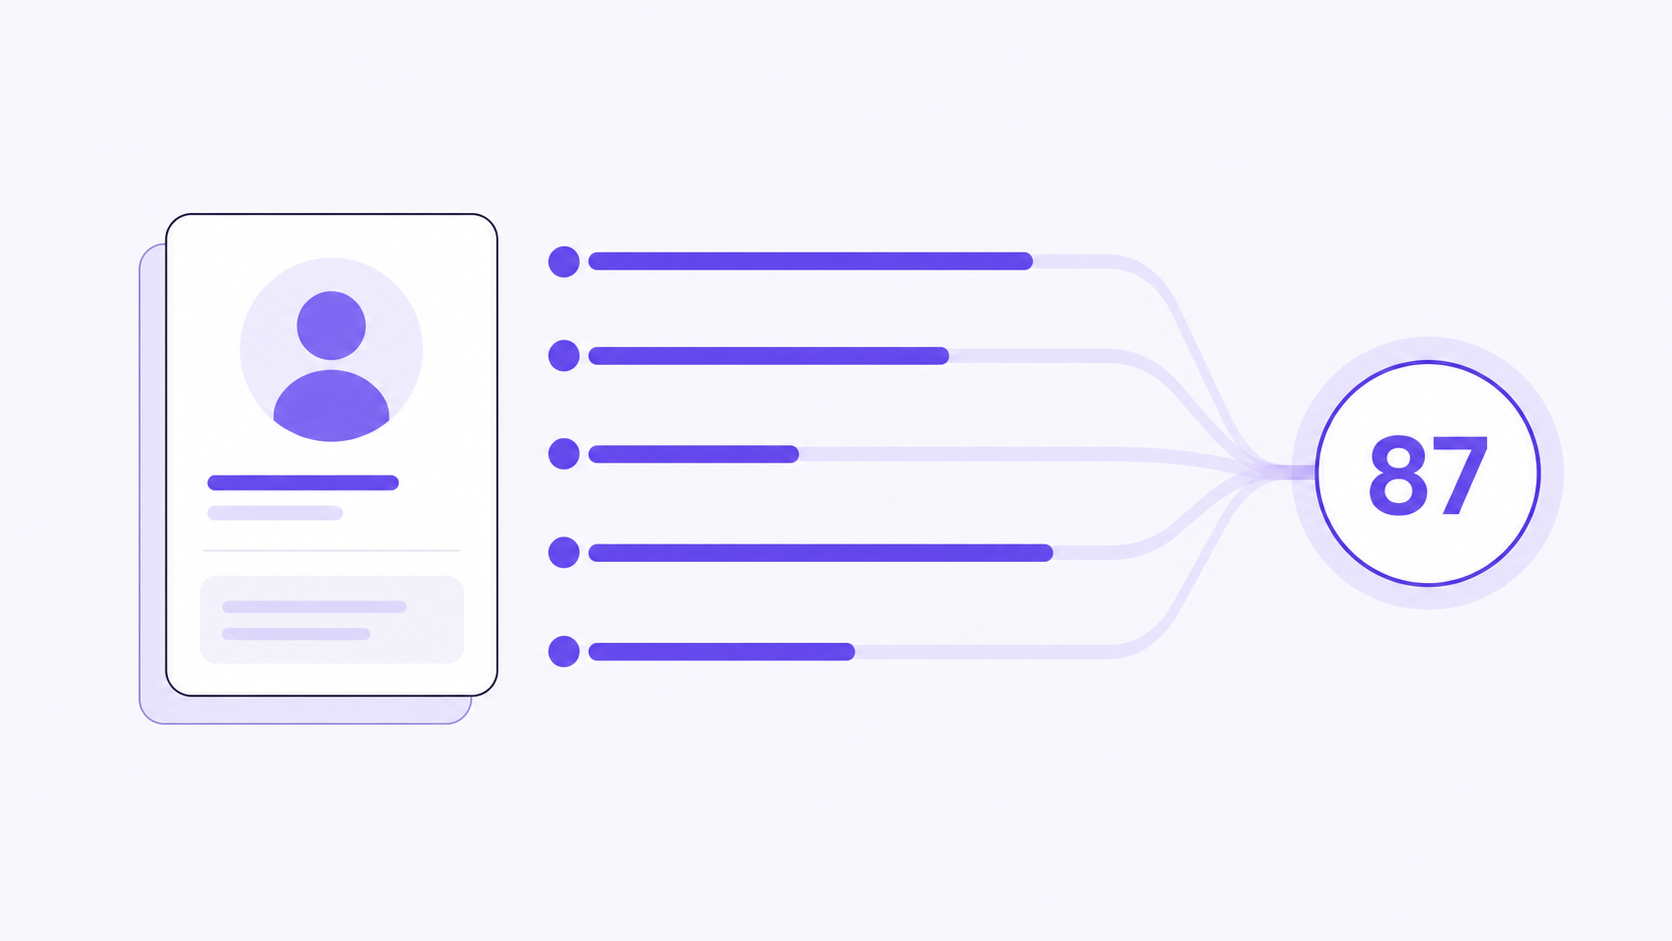
Five signal categories distinguish a referral propensity model from a standard advocacy score. As a 2026 SSRN advocacy readiness preprint argues, signal-based scoring requires combining behavioral, relational and contextual inputs instead of relying on any single proxy.
- Product usage depth: feature adoption breadth, session frequency and workflow integration. Users who run core workflows inside your product daily have both the credibility to recommend it and the evidence to back the recommendation up.
- Relationship tenure and account health: customers past their first renewal, with no open escalations and a clean payment history, are structurally lower-risk referrers.
- Network position: role in purchasing decisions, team size and cross-functional visibility. A director who influenced three vendor decisions in the past year carries more referral weight than an individual contributor, regardless of NPS score.
- Satisfaction and sentiment proxies: NPS tier combined with support ticket pattern and expansion history. A user who upgraded and never filed a complaint reads differently than one who scores the same NPS after two escalations.
- External sharing behavior: community posts, G2 or Capterra reviews, social mentions. Prior public advocacy is the strongest signal that someone will act and follow through, which is why 1st-level referral visibility matters so much in program setup.
How to weight and combine signals into a composite score
Two approaches dominate in practice, and the right choice depends on how much closed-referral data you have.
Points-based weighting
If your referral program is under 12 months old or has fewer than a few hundred closed referral outcomes, start with a points model. Assign weights to each signal category based on your hypothesis about relative importance, then sum them into a 0-100 score:
|
Signal category |
Example weight |
|---|---|
|
Product usage depth |
30 |
|
Network position |
25 |
|
Relationship tenure and health |
20 |
|
Satisfaction proxies |
15 |
|
External sharing behavior |
10 |
Weights are assumptions until validated against outcomes. Revisit them quarterly once referral conversion data accumulates, because low conversion rates are often a sign of a referral program converting under 3% that needs structural fixes.
Regression and gradient-boosted models
With sufficient labeled data, a logistic regression or gradient-boosted classifier produces a calibrated probability estimate instead of an index. As Marketsizer notes for B2B SaaS propensity modeling, combining independent propensity signals produces meaningfully stronger predictions than any single proxy.
Referral datasets have a class imbalance problem: successful conversions are rare relative to the total user base, so standard accuracy metrics mislead. Use precision-recall curves and consider oversampling positive cases or applying class weights during training.
Calibration is the step most teams skip. Validate the score against actual referral conversion history, not sharing rate. Sharing is cheap; conversion is the label that matters.
Building the training dataset from historical referral outcomes
Most B2B SaaS teams hit the same wall when building a referral propensity model: they have referral link data but sparse conversion labels.
Start by defining your positive class precisely. A positive label is a referral that produced a converted, retained customer, not a bare signup. Referrals that reached signup but churned within 60 days are ambiguous and worth excluding from initial training runs.
For dataset construction, segment your historical referrers into three groups: users who referred at least one converting customer, users who shared but produced no conversions, and users who never shared. The second group is as valuable as the first because it gives you negative signal attached to real sharing intent.
When data is too thin to train a classifier
If you have fewer than 300 labeled outcomes, logistic regression will overfit. At that scale, treat the points-based model as your production approach and use historical data only to validate signal weights.
Long sales cycles create a label-timing problem. If your median deal takes four months to close, a referral sent in January may not produce a positive label until May. Set your labeling window to at least 1.5x your median sales cycle, or you will systematically undercount conversions and bias the model toward predicting no-convert.
Niche markets compound this further. When your total addressable user base is a few thousand accounts, supplement internal data with cohort-level behavioral proxies: define a high-propensity cohort using your signal categories and compare product usage and retention patterns against lower-propensity cohorts. The cohort gap validates your weighting logic without requiring conversion-labeled rows.
Applying the score to segment your referrable user base
Once the model produces scores, segment users into three tiers before activating anything.
There are meaningful differences in how each tier responds to referral activation, and treating them identically wastes program economics.
The three tiers
- High-propensity users (top 15 to 20% of scores) get direct, in-product activation. Surface the referral widget at a moment of delight, such as after a successful workflow completion, a milestone hit, or a first expansion event. This pattern is central to in-product referral loops in product-led SaaS. These users have the product depth and network fit to convert referrals; the job is timing the ask correctly.
- Medium-propensity users (middle 40-50%) respond better to nurture than immediate activation. Email sequences tied to usage milestones, or in-app announcements after their next renewal, give them time to build the credibility the score says they don't yet fully have. Prompting too early here produces shares without conversions.
- Low-propensity users should be excluded from referral activation entirely. Adding them to outreach dilutes program economics and trains the model on noise. Exclusion is an active decision, not a passive one.
Score tier also determines which activation surface to use, including whether to deploy multiple referral launchers across touchpoints. High-propensity users with strong peer networks but infrequent logins belong in a dedicated partner pathway, not an in-product widget: they won't see the widget often enough for it to trigger. Medium-propensity power users who log in daily are better candidates for in-product prompts than email, where open rates cap the ceiling on activation.
Timing: when in the customer lifecycle to act on a high score
A high propensity score is a precondition, not an instruction to act. The timing of the activation determines whether a high-scoring user shares or ignores the prompt entirely.
Referral readiness follows value moments, not calendar intervals. Three behavioral events signal that a user has crossed into high-sharing intent: completing a first meaningful outcome inside the product, reaching feature mastery on a core workflow, and experiencing a positive expansion event such as an upgrade or a successful output they can point to externally. A user who just hit that threshold has both the conviction to recommend and something concrete to reference when they do.
Score decay matters here. A user who peaked during onboarding but hasn't logged in for six weeks is a weaker candidate than their score suggests. Build a decay function into your scoring layer: reduce the score multiplier when recent session frequency drops below a threshold, and resurface the user only when a new behavioral event resets their signal. Decayed-score users need a triggering event, not a prompt.
The inverse is equally common. Users suppressed during a support escalation or billing dispute may cross back into high-propensity territory after resolution. A closed ticket combined with a renewal is a strong re-entry signal, and these re-engaged users often become the referred customers with higher LTV that validate your program economics. Track suppressed users as a separate queue and resurface them automatically when suppression conditions clear.
Prompting at the wrong moment is a net negative. A referral ask mid-onboarding, before the user has a result to point to, will be declined and remembered as premature. The goal is to arrive exactly when the user's internal answer to "would I recommend this?" just became yes.
Adjustments for long sales cycles, niche markets and compliance-sensitive verticals
Three adjustments apply when your referral environment doesn't match the standard PLG model.
Sales-led funnels
When the buyer and the product user are different people, usage depth signals the wrong person. The champion who runs the product daily often can't sign a contract. Reweight your model toward network position and organizational seniority, not session frequency. Track who influences deal progression in your CRM and use that as a supplementary signal alongside product engagement.
Niche markets with low user volumes
High referral overlap is the core problem. When your total addressable user base is a few thousand accounts, multiple users often know the same prospect. Your deduplication logic needs a conscious default: Cello rewards the first referrer by default, but in tight professional communities, rewarding the most credible referrer may produce better conversion. Precision matters more than recall here. A false positive that prompts the wrong user damages a relationship you can't easily replace.
Compliance-sensitive verticals
Fintech, legal tech and healthcare-adjacent products operate under referral constraints that change both label definitions and prompt strategy. A referred lead who converts but triggers a compliance review is not a clean positive label. Exclude disputed or reviewed conversions from training data. On the prompt side, in-product cash reward offers may conflict with internal procurement policies at enterprise accounts. Non-cash rewards or organizational-level incentives can produce higher activation rates in compliance-sensitive environments than a direct cash offer would.
Common model failures and how to avoid them
Five failure modes recur across teams that have built referral propensity models and found them underperforming.
Modeling at the account level instead of the user level
Account-level signals like ARR, contract size and renewal rate predict account health, not individual sharing behavior. The user who refers is a person with a network, not a billing record. Fix: join product usage and session data to individual user IDs before feature engineering.
Training on leaky features
If your feature set includes any activity that happens after a referral was made, you've introduced information the model can't have at prediction time. Fix: enforce a strict feature cutoff date anchored to the referral event timestamp.
Class imbalance
If 3% of your users ever made a converting referral, a model that predicts zero referrals achieves 97% accuracy and zero utility. Fix: use precision-recall instead of accuracy as your evaluation metric, and apply class weighting or oversample positive cases during training.
Treating the score as static instead of event-driven
High-scoring users get prompted at the wrong moment or not at all after their score decays. Fix: re-score on a triggered basis whenever a behavioral signal updates (a login, a feature adoption event, a renewal) instead of on a weekly batch cycle.
Building a score with no defined action layer
A score that sits in a dashboard and informs no prompt, no campaign and no suppression rule produces no referrals. Fix: before building the model, define exactly which score threshold triggers which activation surface and who owns that decision.
Activating the score inside your referral program
The score is only useful when it connects to a system that acts on it. Four integration points matter in practice.
Feed score tiers directly into your campaign segmentation layer. High-propensity users enroll in one campaign with immediate in-product activation; medium-propensity users enter a nurture sequence with milestone-based triggers; low-propensity users are excluded entirely. Cello's multi-campaign architecture supports this segmentation by user attributes, so each cohort receives a distinct incentive structure and trigger timing without manual sorting.
Sync high-score cohorts to your CRM for sales team follow-up on accounts with long sales cycles. A high-propensity user at an enterprise account who cannot self-serve a referral link needs a different path than a PLG user who logs in daily. Route those users to your sales or partnership team as warm referral candidates, not to the in-product widget.
Configure trigger timing by product event, not calendar interval. In-product prompts tied to behavioral milestones (workflow completion, first expansion event, renewal confirmation) outperform time-based triggers because they arrive when sharing intent is highest. Cello supports moment-of-delight triggers attached to specific usage events, where score-gated activation and behavioral timing align.
Run A/B tests across matched score tiers before committing to a reward structure. Split users within the same score band across two campaign variants and compare conversion rates. Score tier controls for propensity, so the test isolates program mechanics, not user readiness.
How Cello uses referral propensity logic for user-led growth
Cello's infrastructure is built around the same logic a propensity model produces: different users need different triggers, at different moments, with different incentives.
Behavioral milestone triggers attach referral prompts to specific product events, not static intervals. Across Cello's customer base, moments-of-delight prompts produce meaningfully higher sharing rates compared to static launcher placement. The same user, prompted at the right moment, behaves completely differently than when prompted at a fixed day-30 interval.
Multi-campaign segmentation by user attributes handles the cohort separation the model produces. High-propensity users enter one campaign with immediate in-product activation; medium-propensity users route into a nurture sequence with milestone-based triggers; low-propensity users are excluded. Each cohort runs distinct incentive structures and timing rules within the same account, without manual sorting.
The outcomes follow: VEED reduced CAC by 90.4% versus paid acquisition after embedding Cello in-product. Xentral grew Referral ARR by running a structured referral program with rewards calibrated to their ACV.
The Performance Benchmarks module surfaces which cohorts are driving active sharing, conversions and revenue, giving growth operators the feedback loop needed to adjust score thresholds and campaign targeting over time. The AI Assistant adds a natural-language query layer on top of that data, so refining the segmentation does not require a dedicated data science function.
Final thoughts on using referral propensity scores in B2B SaaS
A well-built referral propensity score changes who you prompt, when you prompt them and what you ask them to do, which are three variables that most programs treat as fixed. The signal categories covered here give you a working foundation: layer in your own conversion data, revisit the weights quarterly and build score decay in from the start. The model without an action layer is just a spreadsheet. Start with Cello to connect propensity scoring directly to in-product activation and campaign segmentation.
How do you build a referral propensity score for B2B SaaS when you have fewer than 300 labeled referral outcomes?
Start with a points-based model instead of a classifier. Assign weights across five signal categories (product usage depth, network position, relationship tenure and account health, satisfaction proxies, and external sharing behavior) and sum them into a 0-100 index. Use historical referral data only to validate your signal weights, not to train a regression. Once you accumulate roughly 300 or more closed referral outcomes, you have enough labeled data to move to logistic regression or a gradient-boosted model that produces a calibrated conversion probability instead of an index.
What signals actually predict referral conversion in B2B SaaS, and why does NPS fail here?
Product usage depth, network position and external sharing behavior are the strongest predictors of whether a referral will convert, not NPS score. NPS measures abstract advocacy intent; it says nothing about whether a user's network contains ICP-fit buyers, whether they operate in a compliance environment that restricts vendor recommendations, or whether they have accumulated enough peer credibility for a recommendation to land. Two users can both score 9 on NPS and produce completely different referral outcomes. The one who quietly runs their entire workflow inside your product and refers three paying customers will often score no higher than the one who never refers anyone.
How should I segment my user base once a referral propensity score is built?
Split users into three tiers before activating anything. High-propensity users, meaning the top 15 to 20% of scores, get direct, in-product activation timed to a behavioral milestone such as a workflow completion or expansion event. Mid-propensity users in the middle 40 to 50% respond better to milestone-based nurture sequences than to immediate prompting; activating them too early produces shares without conversions. Low-propensity users should be excluded from referral activation entirely, since adding them to outreach dilutes program economics and introduces noise into your conversion labels. Cello's multi-campaign architecture supports this three-tier segmentation by user attributes, so each cohort receives distinct incentive structures and trigger timing without manual sorting.
What adjustments does a referral propensity model need for niche B2B SaaS markets with long sales cycles?
Two adjustments matter most. First, set your labeling window to at least 1.5 times your median sales cycle. If your median deal closes in four months, a referral sent in January may not produce a positive label until May, and a shorter window will systematically undercount conversions and bias the model toward predicting no-convert. Second, in tight professional communities where multiple users know the same prospect, your deduplication logic needs a conscious default: rewarding the first referrer is standard, but in high-overlap niche markets, rewarding the most credible referrer may produce better conversion outcomes. Precision matters more than recall when a false positive that prompts the wrong user damages a relationship you cannot easily replace.
I'm Head of Growth at a B2B SaaS. Our referral program launched six months ago but conversion is under 3%. What should I check first?
Check launcher visibility and activation timing before changing reward structures. A launcher that users cannot find, whether buried in a dropdown or placed outside core workflow screens, suppresses the Active Rate before any sharing or conversion activity can occur, making conversion look like a reward problem when it is actually a placement problem. Second, check whether your activation prompts are firing at behavioral milestones or at fixed calendar intervals: prompting at a static day-30 trigger instead of after a meaningful product outcome will generate low-intent shares that rarely convert. In Cello, moments-of-delight triggers tied to specific product events produce up to 3.4 times higher sharing rates compared to static launcher placement. The same user, prompted at the right moment, behaves completely differently.
What's the difference between a referral propensity score and a standard lead score in B2B SaaS?
A referral propensity score predicts which users will produce a referral that converts to a paying customer, while a lead score predicts who will buy. Lead scoring weights pricing page visits and demo requests because those signals predict purchase intent; referral propensity modeling weights product usage depth, network position and external sharing behavior because those signals predict whether a recommendation will land with an ICP-fit buyer. The two models target different people in your user base and should never be conflated.
How does a referral propensity score work for a sales-led B2B SaaS with a long enterprise cycle and multiple decision makers?
In sales-led funnels where the product user and the contract signer are different people, you reweight the model away from session frequency toward network position and organizational seniority. Track who influences deal progression in your CRM alongside product engagement, and set your conversion label window to at least 1.5 times your median sales cycle so you do not systematically undercount closed referrals. High-propensity users at enterprise accounts who cannot self-serve a referral link should be routed to your sales or partnership team as warm referral candidates rather than to an in-product widget.
Should I use percentage-based or flat-fee referral rewards for a high-ACV B2B SaaS product?
Percentage-based rewards with a cap are the more common structure for high-ACV B2B SaaS because they scale with deal size without creating uncapped liability — a $200 reward on a $2,000 ACV deal is structurally different economics than the same reward on a $20,000 ACV deal. Flat-fee rewards reduce integration complexity when your billing system does not expose granular revenue data, but a single campaign cannot hold distinct flat-fee amounts per subscription tier; you need a separate campaign per tier. The right choice depends on whether your deal economics are consistent enough that a single cap works across your customer base.
How do I position a referral incentive program to B2B customers in compliance-sensitive industries who feel that product recommendations should be based on merit, not financial reward?
Non-cash reward structures — subscription credits, free months, feature unlocks, training vouchers or organizational-level discounts applied to the company account — remove the perception that an individual employee is being paid to recommend a vendor, which is the core compliance concern. For enterprise accounts with strict procurement policies, organizational-level rewards that credit the referring company's subscription rather than the individual referrer's PayPal account align the incentive with business value rather than personal gain. Framing the program as a loyalty benefit for advocates, not a sales commission, consistently outperforms direct cash framing in regulated and trust-sensitive verticals
What referral activation and sharing rates should a B2B SaaS company realistically expect from a propensity-score-gated program?
Activation and sharing rates vary materially based on launcher visibility, prompt timing and how tightly the program is gated to high-propensity users. Across Cello's customer base, behavioral milestone triggers tied to specific product events produce up to 3.4 times higher sharing rates compared to static launcher placement with no propensity gating. The Active Rate benchmark — Active Referrers divided by Enabled Referrers — is the first metric to watch, because low launcher discoverability suppresses it before any sharing or conversion activity can occur. Programs where the launcher is difficult to find consistently show low Active Rates regardless of how strong the underlying propensity signal is.
Can a referral propensity model work for early-stage B2B SaaS with fewer than 500 users?
Yes, but you use a points-based model rather than a trained classifier. With a small user base you will not have enough labeled conversion outcomes to train a regression without overfitting, so you assign weights across the five signal categories — product usage depth, network position, relationship tenure, satisfaction proxies and external sharing behavior — and validate those weights against whatever closed referral history you have. Cohort-level behavioral proxies fill the gap: compare product usage and retention patterns between users you classify as high-propensity versus low-propensity to confirm the weighting logic produces a meaningful separation before you act on the scores.
What is score decay in a referral propensity model and why does it matter?
Score decay is a function that reduces a user's propensity score multiplier when recent session frequency drops below a defined threshold, preventing you from prompting a user whose last meaningful engagement was weeks ago based on a score that reflected a different behavioral state. A user who peaked during onboarding but has not logged in for six weeks is a weaker referral candidate than their raw score suggests, and prompting them wastes program economics. Re-score on a triggered basis whenever a behavioral signal updates — a login, a feature adoption event, a renewal — rather than on a weekly batch cycle, so decayed scores are reset by real activity rather than by a calendar.
How do you handle class imbalance when training a B2B SaaS referral propensity model?
If only 3% of your users ever produced a converting referral, a model that predicts zero referrals achieves 97% accuracy and zero practical utility. Use precision-recall curves as your evaluation metric instead of accuracy, and apply class weighting or oversample positive cases during training to force the model to treat the rare converting-referral label as the outcome that matters. Calibrate the score against actual referral conversion history — not sharing rate — because sharing is a cheap signal that does not track closely with whether a recommendation closes a paying customer.
Why should you exclude low-propensity users from referral activation entirely rather than just giving them a lower-priority prompt?
Including low-propensity users in referral outreach dilutes program economics in two ways: it produces shares without conversions that add cost to your program while contributing noise to your conversion labels, making it harder to validate and improve your model over time. A referral ask mid-onboarding, before a user has a meaningful result to reference, will be declined and remembered as premature — which makes that user less likely to respond to a correctly-timed prompt later. Exclusion is an active decision that protects both the economics of the current program and the quality of the data you use to improve future targeting
How do you define the positive class label when building a training dataset for a B2B SaaS referral propensity model?
A positive label is a referral that produced a converted, retained customer — not a bare signup. Referrals that reached signup but churned within 60 days are ambiguous enough to exclude from initial training runs, because including them trains the model on conversions that do not reflect the economic outcome you are trying to predict. Segment your historical referrers into three groups: users who referred at least one converting retained customer, users who shared but produced no conversions, and users who never shared. The second group is as valuable as the first because it provides negative signal attached to real sharing intent, helping the model distinguish propensity to share from propensity to convert.